Head to head / curated pair / cycle 04
Cursor vs Kiro
Both products were given the identical 9 prompt vibeOps specification, 5 times each. Nothing on this page is an impression, all of it is a measurement from the same harness.
The strongest edit loop we measured. It keeps a large working set in view, so the tenancy constraint from prompt 3 survived every later change without being restated. As a coding agent it produces no interface of its own, which caps the design subscore: what you get is exactly the quality of the framework and components you point it at. Everything it writes lands in your repository, so ownership is total.
Writes a specification and a task list before it writes code, which costs it roughly a third more wall clock than the fastest agents and buys back one of the tightest duration spreads in the index. The specification step is why prompt 2 came out correct in five of five runs: the tenancy rule was written down before anything depended on it.
Index gap
2.25
Cursor leads
Axes won
7 / 2
Cursor versus Kiro, of 9 axes
Lower turn latency
Cursor
53.4 s per prompt
Higher pass rate
Kiro
93.3%
Every measurement, side by side
Cyan marks the better figure on each row. The delta column is the first product minus the second.
| Measurement | Cursor | Kiro | Delta |
|---|---|---|---|
| Composite index | 77.92 | 75.67 | +2.25 |
| Agent performance (weight 18.55) | 92.0 | 84.0 | +8.00 |
| Reliability (weight 18.56) | 86.7 | 93.3 | -6.60 |
| Scalability (weight 13.4) | 82.0 | 80.0 | +2.00 |
| SEO and GEO (weight 12.37) | 58.0 | 60.0 | -2.00 |
| API and MCP (weight 9.28) | 74.0 | 72.0 | +2.00 |
| Integrations (weight 8.25) | 80.0 | 74.0 | +6.00 |
| Design output (weight 7.22) | 66.0 | 65.0 | +1.00 |
| Turn latency score (weight 7.22) | 58.8 | 43.4 | +15.40 |
| Value (weight 5.15) | 80.0 | 78.0 | +2.00 |
| Median turn latency, seconds per prompt | 53.4 | 72.4 | -19.00 |
| p10 seconds | 28.7 | 49.1 | -20.40 |
| p90 seconds | 82.7 | 140.4 | -57.70 |
| Full spec, minutes, derived | 8.0 min | 10.9 min | -2.90 |
| Executions failed | 3 | 1 | +2.00 |
| HTML bytes, no JS | 24.0 KB | 22.0 KB | +2.0 KB |
| LCP milliseconds | 1,720 | 1,800 | -80.00 |
| CLS | 0.030 | 0.040 | -0.01 |
| Entry price | USD 20 / month | USD 20 / user / month | n/a |
Screenshot diff
Both landing pages, captured by the lab on 14 Aug 2026 at 1440 by 900. Stored locally, never hotlinked.
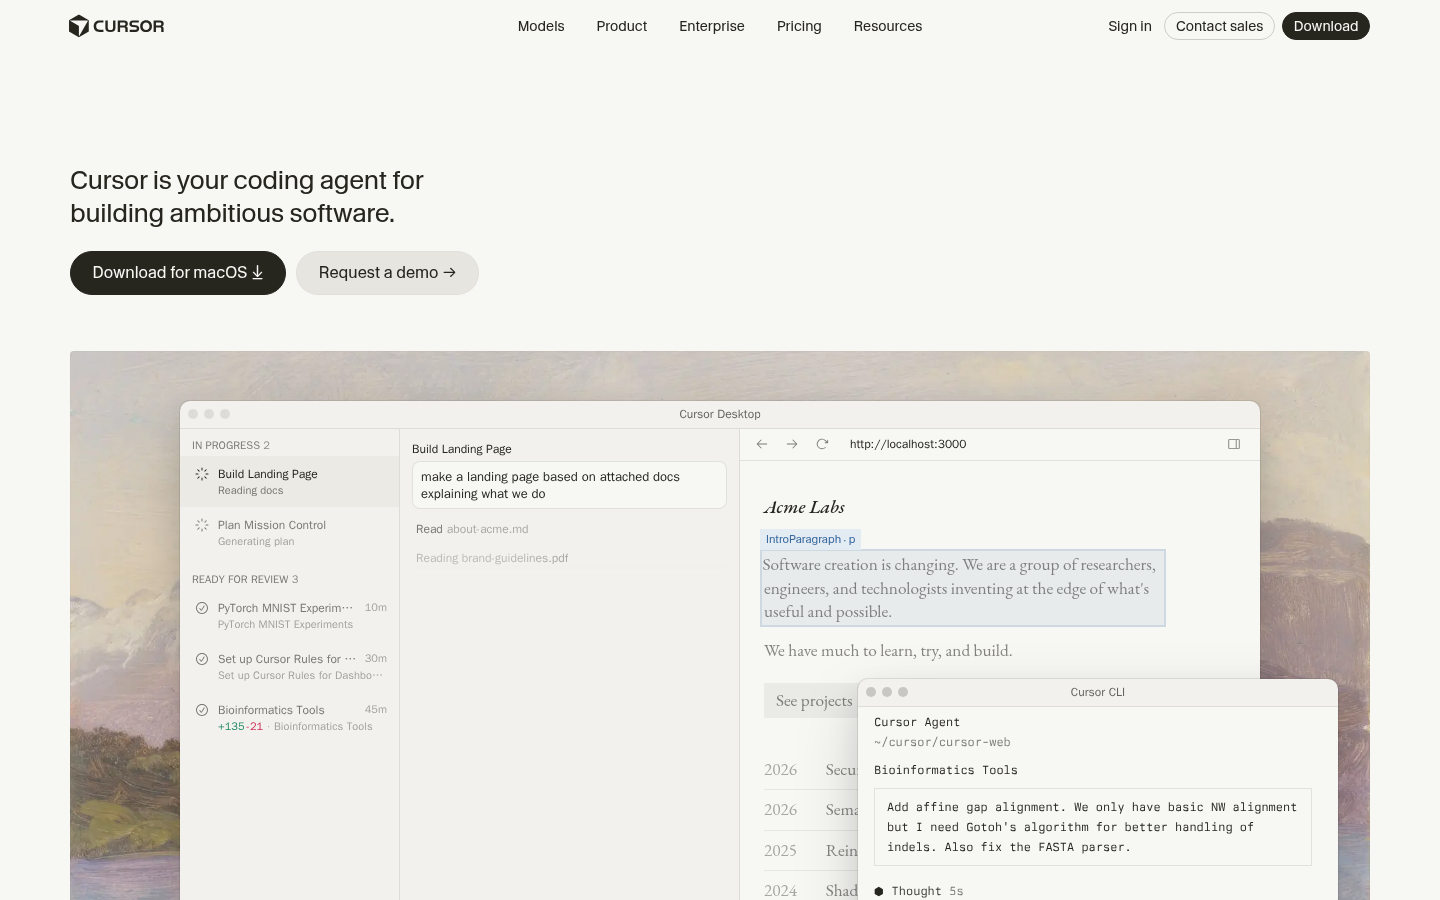
Cursor, captured 14 Aug 2026.
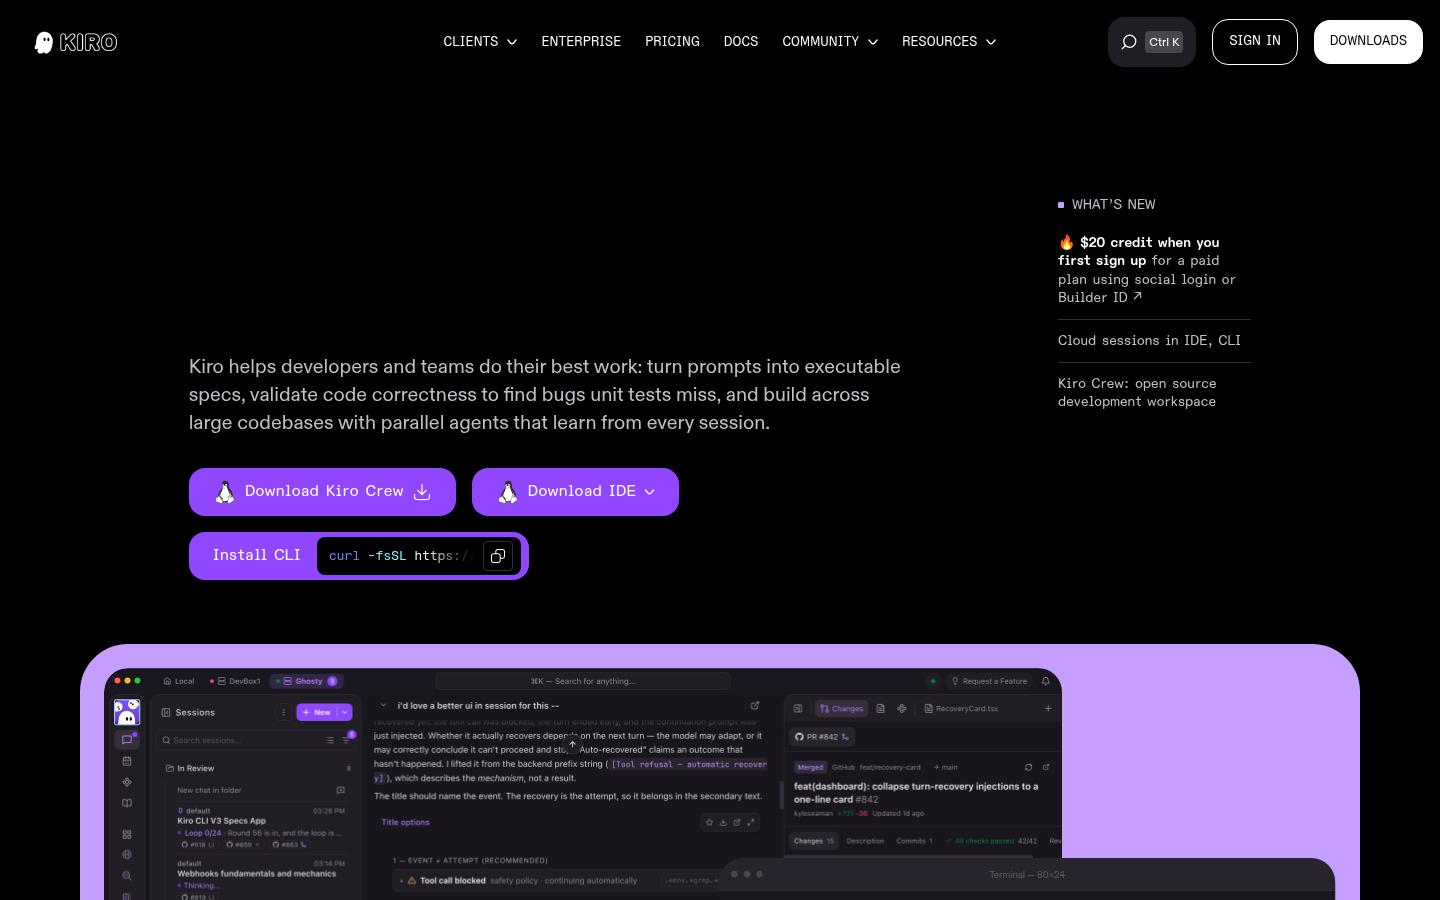
Kiro, captured 14 Aug 2026.
Speed spread on a shared scale
Cursor
28.7 / 53.4 / 82.7 seconds
Kiro
49.1 / 72.4 / 140.4 seconds
Axis by axis, who wins
Cursor wins 7 of 9
- Agent performance92.0
- Scalability82.0
- API and MCP74.0
- Integrations80.0
- Design output66.0
- Turn latency score58.8
- Value80.0
Kiro wins 2 of 9
- Reliability93.3
- SEO and GEO60.0
Verdict
Cursor takes the composite by 2.25 points. It wins on the weighted total, but the axis table is where the real decision sits: Cursor takes 7 axes and Kiro takes 2.
If the work in front of you is mostly interface, weight the design and turn latency rows. If it is a product with an API, webhooks and background jobs, weight agent performance, reliability and the API and MCP row, which together carry 46.39 of the 100 index points on this board. This board does not score code ownership: a coding agent edits a repository you already own, so that property is never the vendor's to grant.
Both products in this comparison were measured in the same cycle, on the same specification, by the same harness. The per run data for each is on its product page and in /api/runs.json.