Full-stack app builders / rank 17 of 20 / cycle 04
bolt.diy benchmark
The community built sibling of a commercial product, and the gap between them is the point of measuring it: same interaction model, noticeably less polish in the agent loop. It has one of the widest p10 to p90 spreads in the index, because a run that picks up the wrong model configuration behaves nothing like one that does not. Worth the entry for anyone who needs the whole stack under their own control.
Composite index
59.85
of 100 | withheld vs. cycle 03
Delta not shown for cycle 04: the roster was re-based from one merged ranking into two class boards, so cycle 03 and cycle 04 ranks are not on the same scale. Resumes cycle 05.
At a glance
Composite index
59.85
rank 17 of 20
Rank
#17
of 20 on the full-stack app builders board
Median turn latency
113.8 s per prompt
17.1 min across the full nine prompt spec, derived
Reliability
55.6%
strict pass rate
SEO score
62.0
0 to 100, SEO and GEO axis
Three strongest axes
- Code ownership97.0
- Value82.0
- Design output74.0
Three weakest axes
- API and MCP48.0
- Scalability52.0
- Integrations54.0
Median turn latency
113.8 s per prompt
p10 59.6 s, p90 231.5 s
Strict pass rate
55.6%
25 pass, 10 partial, 10 fail
Executions recorded
45
5 runs of 9 prompts
Entry price
No licence fee, bring your own model key
Vendor's own unit and billing period. Never a currency conversion
Per axis subscores
Composite recomputed from these 10 rows: 59.85. That is the arithmetic behind the index, and you can repeat it by hand. Rounding rule: half up at two decimals, applied uniformly to all 37 published products.
| Axis | Subscore 0 to 100, tick is the roster median | Score | Median | Weight % | Contribution |
|---|---|---|---|---|---|
| Agent performance | 60.0 | 71.5 | 18 | 10.80 | |
| Reliability | 55.6 | 71.1 | 18 | 10.01 | |
| Scalability | 52.0 | 66.0 | 13 | 6.76 | |
| SEO and GEO | 62.0 | 63.5 | 12 | 7.44 | |
| API and MCP | 48.0 | 58.0 | 9 | 4.32 | |
| Integrations | 54.0 | 65.0 | 8 | 4.32 | |
| Design output | 74.0 | 78.5 | 7 | 5.18 | |
| Turn latency score | 57.3 | 66.5 | 7 | 4.01 | |
| Value | 82.0 | 74.0 | 5 | 4.10 | |
| Code ownership | 97.0 | 73.0 | 3 | 2.91 |
Turn latency distribution
Every recorded prompt duration for bolt.diy, in seconds. Median wall clock time for one prompt, not for a whole build. The cyan tick on the whisker is the median.
Spread against the cohort
p10 59.6 s / median 113.8 s / p90 231.5 s
Scale is shared with every product in the cohort, so the bars are directly comparable between pages. Ratio of p90 to median is 2.03x.
Outcome split
25 pass / 10 partial / 10 fail
SEO and GEO measurements
Taken from the public marketing page this product generated in prompt 8, fetched with JavaScript disabled.
HTML bytes, no JS
15.0 KB
15,360 bytes of real text content with scripts blocked
LCP
2,320 ms
Throttled connection, cold cache
CLS
0.080
Cumulative layout shift on load
SEO and GEO subscore
62.0
0 to 100, worth 12 index points on this board
Raw run data: 45 executions
One row per prompt execution. Nothing is aggregated away, nothing is hidden, including the failures.
| Run | Prompt | Prompt target | Started | Duration (s) | Outcome | Note |
|---|---|---|---|---|---|---|
| R01 | P01 | Tenant and user model | 11 Aug 2026 08:00 UTC | 82.8 | partial | Delivered the main path, missed the boundary case named in the pass criteria. |
| R01 | P02 | Authentication and session | 11 Aug 2026 08:03 UTC | 98.4 | fail | Agent looped on the same edit for the full timeout window of 20 minutes. |
| R01 | P03 | Projects CRUD with tenancy | 11 Aug 2026 08:07 UTC | 211.5 | pass | |
| R01 | P04 | Public REST API with keys | 11 Aug 2026 08:12 UTC | 75.5 | fail | Agent looped on the same edit for the full timeout window of 20 minutes. |
| R01 | P05 | Outbound webhooks with signatures | 11 Aug 2026 08:15 UTC | 40.3 | partial | Webhook delivered unsigned. The retry ladder was written only after an explicit follow up. |
| R01 | P06 | Background jobs | 11 Aug 2026 08:18 UTC | 230.3 | pass | |
| R01 | P07 | Admin panel | 11 Aug 2026 08:24 UTC | 161.8 | partial | Required one clarifying instruction before the criterion was met. |
| R01 | P08 | Public marketing surface | 11 Aug 2026 08:29 UTC | 127.6 | pass | |
| R01 | P09 | Hardening pass | 11 Aug 2026 08:33 UTC | 112.9 | pass | |
| R02 | P01 | Tenant and user model | 12 Aug 2026 08:00 UTC | 65.4 | fail | Run picked up a model configuration that could not hold the whole prompt. Abandoned after three failed edits. |
| R02 | P02 | Authentication and session | 12 Aug 2026 08:03 UTC | 57.4 | fail | Agent looped on the same edit for the full timeout window of 20 minutes. |
| R02 | P03 | Projects CRUD with tenancy | 12 Aug 2026 08:06 UTC | 129.7 | partial | Pagination off by one at the final page boundary. |
| R02 | P04 | Public REST API with keys | 12 Aug 2026 08:10 UTC | 174.2 | pass | |
| R02 | P05 | Outbound webhooks with signatures | 12 Aug 2026 08:15 UTC | 52.0 | partial | Error envelope inconsistent between two of the endpoints. |
| R02 | P06 | Background jobs | 12 Aug 2026 08:17 UTC | 65.6 | fail | Deployed URL returned 500 on every request. |
| R02 | P07 | Admin panel | 12 Aug 2026 08:21 UTC | 149.8 | pass | |
| R02 | P08 | Public marketing surface | 12 Aug 2026 08:25 UTC | 113.8 | partial | Error envelope inconsistent between two of the endpoints. |
| R02 | P09 | Hardening pass | 12 Aug 2026 08:29 UTC | 64.0 | pass | |
| R03 | P01 | Tenant and user model | 13 Aug 2026 08:00 UTC | 56.7 | pass | |
| R03 | P02 | Authentication and session | 13 Aug 2026 08:02 UTC | 60.4 | pass | |
| R03 | P03 | Projects CRUD with tenancy | 13 Aug 2026 08:05 UTC | 129.9 | pass | |
| R03 | P04 | Public REST API with keys | 13 Aug 2026 08:10 UTC | 220.0 | partial | Pagination off by one at the final page boundary. |
| R03 | P05 | Outbound webhooks with signatures | 13 Aug 2026 08:15 UTC | 221.5 | pass | |
| R03 | P06 | Background jobs | 13 Aug 2026 08:21 UTC | 232.3 | pass | |
| R03 | P07 | Admin panel | 13 Aug 2026 08:27 UTC | 119.5 | pass | |
| R03 | P08 | Public marketing surface | 13 Aug 2026 08:31 UTC | 67.3 | partial | Error envelope inconsistent between two of the endpoints. |
| R03 | P09 | Hardening pass | 13 Aug 2026 08:34 UTC | 59.0 | pass | |
| R04 | P01 | Tenant and user model | 14 Aug 2026 08:00 UTC | 91.0 | fail | Run picked up a model configuration that could not hold the whole prompt. Abandoned after three failed edits. |
| R04 | P02 | Authentication and session | 14 Aug 2026 08:03 UTC | 266.6 | pass | |
| R04 | P03 | Projects CRUD with tenancy | 14 Aug 2026 08:09 UTC | 159.2 | pass | |
| R04 | P04 | Public REST API with keys | 14 Aug 2026 08:14 UTC | 160.2 | fail | Build did not start after deploy. Recorded as a fail with the log preserved. |
| R04 | P05 | Outbound webhooks with signatures | 14 Aug 2026 08:19 UTC | 162.8 | partial | Validation added on the write path only. Read path left unguarded. |
| R04 | P06 | Background jobs | 14 Aug 2026 08:23 UTC | 180.3 | pass | |
| R04 | P07 | Admin panel | 14 Aug 2026 08:29 UTC | 193.3 | fail | Build did not start after deploy. Recorded as a fail with the log preserved. |
| R04 | P08 | Public marketing surface | 14 Aug 2026 08:34 UTC | 71.5 | pass | |
| R04 | P09 | Hardening pass | 14 Aug 2026 08:37 UTC | 100.2 | pass | |
| R05 | P01 | Tenant and user model | 15 Aug 2026 08:00 UTC | 69.5 | fail | Deployed URL returned 500 on every request. |
| R05 | P02 | Authentication and session | 15 Aug 2026 08:03 UTC | 82.6 | pass | |
| R05 | P03 | Projects CRUD with tenancy | 15 Aug 2026 08:06 UTC | 98.4 | pass | |
| R05 | P04 | Public REST API with keys | 15 Aug 2026 08:10 UTC | 260.2 | fail | Agent looped on the same edit for the full timeout window of 20 minutes. |
| R05 | P05 | Outbound webhooks with signatures | 15 Aug 2026 08:16 UTC | 168.5 | partial | Webhook delivered unsigned. The retry ladder was written only after an explicit follow up. |
| R05 | P06 | Background jobs | 15 Aug 2026 08:21 UTC | 362.5 | pass | |
| R05 | P07 | Admin panel | 15 Aug 2026 08:29 UTC | 284.8 | pass | |
| R05 | P08 | Public marketing surface | 15 Aug 2026 08:36 UTC | 95.3 | pass | |
| R05 | P09 | Hardening pass | 15 Aug 2026 08:39 UTC | 83.5 | pass |
Pricing
Free and open source, community maintained. You supply the model key.
- Entry price
- No licence fee, bring your own model key
- Priced from
- vendor pricing page
- Value subscore
- 82.0
- Index points per euro
- No licence fee
Entry price is the vendor's own published figure, fetched 21 Aug 2026, never a currency conversion. The currency label is the vendor's own except where the pricing note above records that this lab inferred it. Index points per euro is computed from a separate, euro-normalised figure used only for the Value axis: Converted at the European Central Bank euro reference rate of 1.1699 US dollars to the euro, August 21, 2026.
Capabilities as measured
- stack
- Local or self hosted, framework of your choice
- deploy
- Self hosted
- database
- Bring your own
- auth
- Bring your own
- background jobs
- Whatever you install
- webhooks
- Hand written
- rest api
- Hand written
- mcp server
- Community support
- export code
- Fully open source
- custom domain
- Your hosting decides
- ssr
- Your framework decides
Screenshot
bolt.diy landing page, captured by the lab on 14 Aug 2026 at 1440 by 900. Stored locally, never hotlinked.
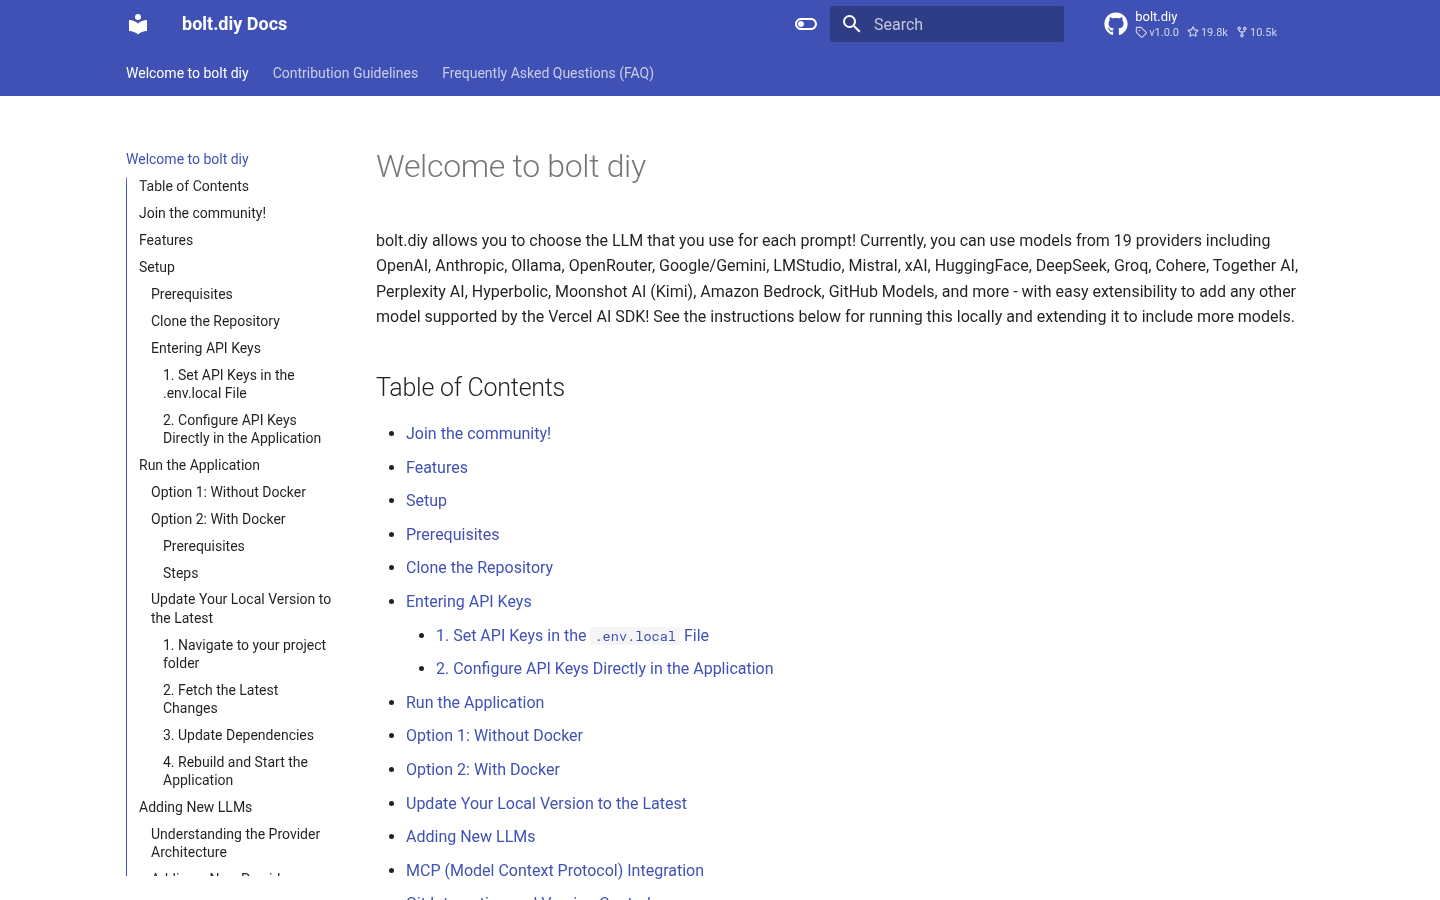
bolt.diy, captured 14 Aug 2026.
Sources and fetch dates
Every claim on this page traces to one of these.
| Source | URL | Fetched |
|---|---|---|
| bolt.diy pricing page | https://github.com/stackblitz-labs/bolt.diy/pricing | 14 Aug 2026 |
| bolt.diy product site | https://github.com/stackblitz-labs/bolt.diy | 14 Aug 2026 |
| LLM Tier run harness output | https://www.llm-tier.com/api/runs.json | 14 Aug 2026 |
Rich results carry this composite as 3.0 on a 0 to 5 scale because that is the only scale the format accepts. The number on this page, 0 to 100, is the real one.
bolt.diy head to head
Reader index
Voted by readers with an account, one score per person per axis. Published beside the lab index, never inside it.
Reader index
not rated yet
Lab index
59.85
2 readers have scored 100% of the index weight so far. A reader index is published at 3 voters and 50% coverage.
Seeded at launch
The reader scores, lab notes and open ratings published here were written by this lab in August 2026 to populate the reader column before the site had readers. They are not customer submissions, they are not vendor supplied and nobody was paid for them. Anything submitted since then comes from a registered account. The lab index is measured from logged runs and is unaffected either way.
| Axis | Weight | Lab | Readers | Votes | Reader mean |
|---|---|---|---|---|---|
| Agent performance | 18% | 60.0 | 65.5 | 2 | |
| Reliability | 18% | 55.6 | 54.5 | 2 | |
| Scalability | 13% | 52.0 | 43.0 | 1 | |
| SEO and GEO | 12% | 62.0 | 65.0 | 2 | |
| API and MCP | 9% | 48.0 | 45.5 | 2 | |
| Integrations | 8% | 54.0 | 59.0 | 2 | |
| Design output | 7% | 74.0 | 77.0 | 2 | |
| Turn latency score | 7% | 57.3 | 31.5 | 2 | |
| Value | 5% | 82.0 | 95.0 | 2 | |
| Code ownership | 3% | 97.0 | 100.0 | 2 |
The reader index is a weighted mean of reader submitted axis scores using the published index weights, renormalised over the axes readers have scored. It is never blended into the lab index. How this works.
Open rating mean
n/a
0 published open ratings, submitted without an account
Lab index
59.85
Measured, not voted
Gap to the measurement
n/a
Positive means open raters put it above the measurement
What agent performance looked like in practice
The community built sibling of a commercial product, and the gap between them is the point of measuring it: same interaction model, noticeably less polish in the agent loop. It has one of the widest p10 to p90 spreads in the index, because a run that picks up the wrong model configuration behaves nothing like one that does not. Worth the entry for anyone who needs the whole stack under their own control.
Across 45 recorded executions this product met the published pass criterion cleanly 25 times, partially 10 times and failed 10 times. The rows above carry the reviewer note for every non clean outcome, which is the only way to tell a product that fails loudly from one that fails quietly.